

How we built spindle's new QEMU-based microVM engine
China Just Built What NVIDIA Feared Most. I Saw It
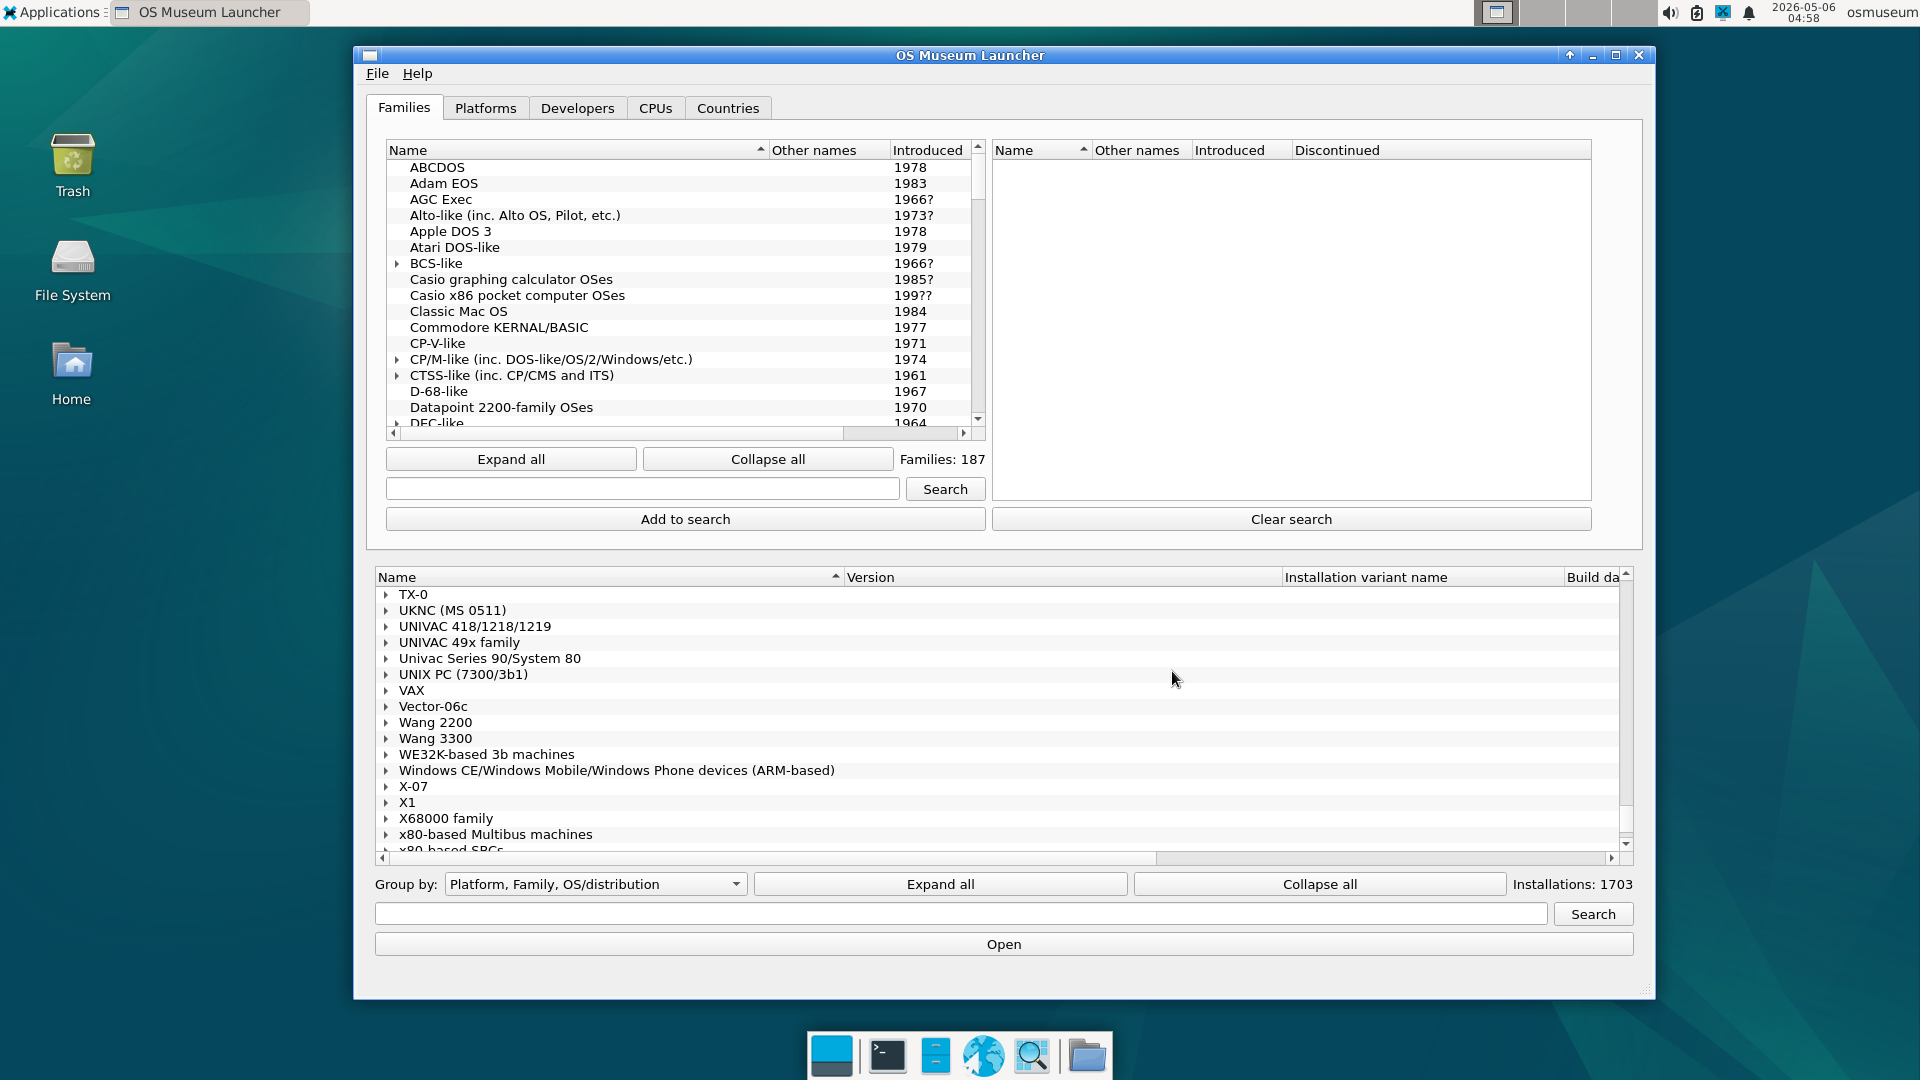
The Virtual OS Museum
Over 1,700 pre-installed operating systems spanning 1948 to today, in a single Linux VM. Bundled QEMU, VirtualBox, and UTM. One-click launchers for Windows and Linux.
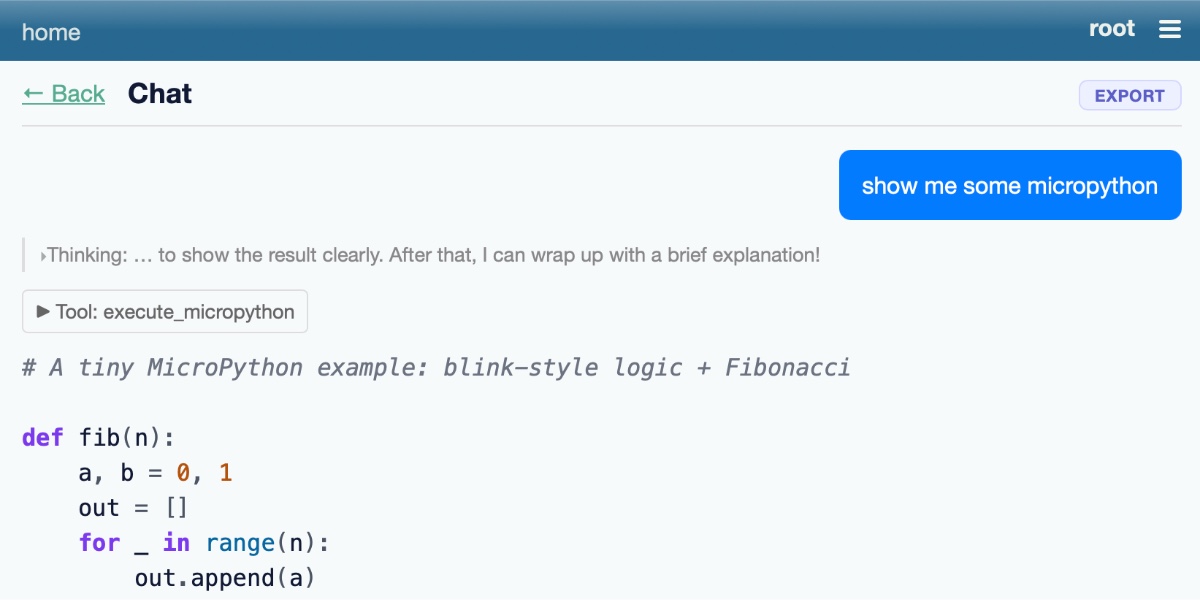
Running Python code in a sandbox with MicroPython and WASM
I’ve been experimenting with different approaches to running code in a sandbox for several years now, but my latest attempt feels like it might finally have all of the characteristics …
Crossing the Hyper-Thread Boundary - exe.dev blog
Your VMs can share a CPU core. You get to decide who they share it with.
Setting up a virtual machine with GPU passthrough
A guide for configuring NixOS with nvidia GPU passthrough to a virtual machine in virt-manager.
How to Fix OpenClaw's Memory Search with QMD | Jose Casanova
Upgrade OpenClaw's memory search from basic SQLite to QMD — a local hybrid search engine combining BM25, vector search, and LLM re-ranking for better AI memory.
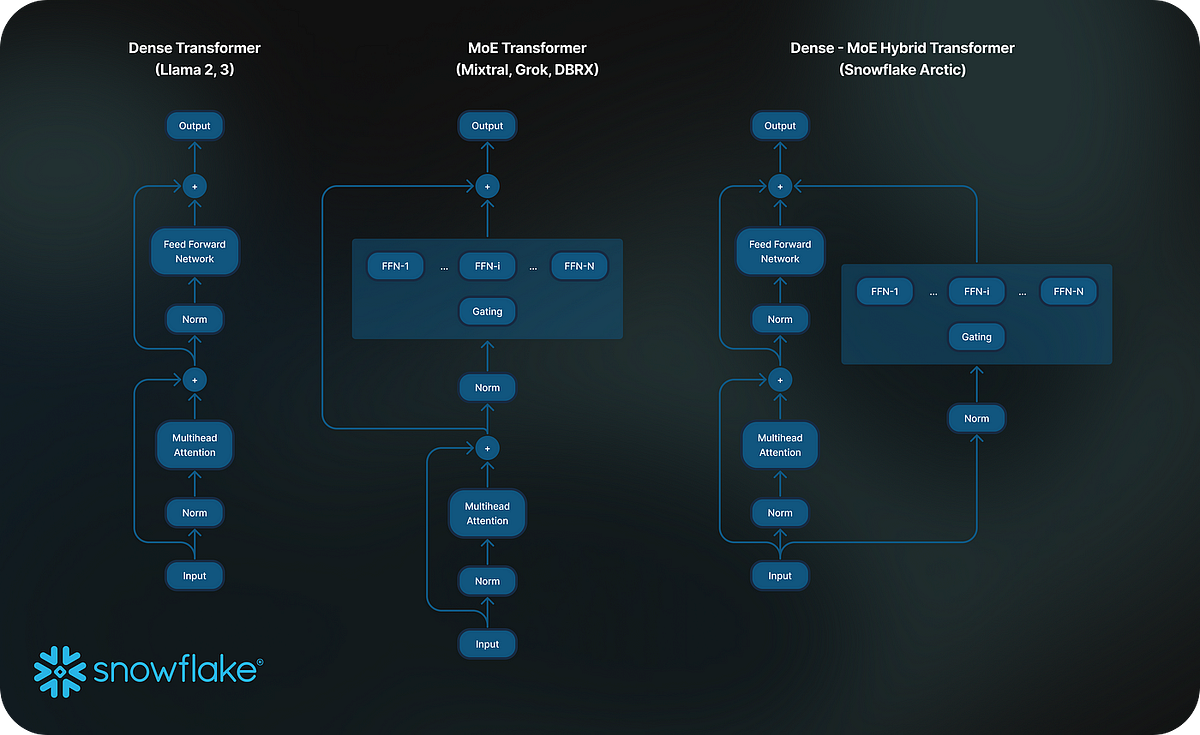
How LLMs Actually Work
A from-the-ground-up walkthrough of how modern LLMs work, from tokens to transformer blocks to the next-token loop
What the AI Wizard taught us about LLM code generation at scale - PostHog
You know what’s boring? Writing integrations. It’s a task you’ll do once, but you always need to do it right, which means carefully reading docs…
Welcome to the Strix Halo Wiki!
Welcome to the Strix Halo Wiki! The purpose of this website it to gather important information and practical guides for systems powered by AMD Ryzen AI MAX and MAX+ processors. Our guides cover various topics and of course there is a separate section…
The machines are fine. I'm worried about us.
On AI agents, grunt work, and the part of science that isn't replaceable.
Qwen3.6 now runs 2x faster with MTP GGUFs! Run locally on just 18GB RAM. ⚡️ MTP enables Qwen3.6 to generate ~1.4–2.2× faster with no accuracy change. Qwen3.6-27B MTP runs at 160 tokens/s. 35B-A3B reaches 240 t/s. GGUFs: huggingface.co/unsloth/Qwen3.6-27B-MTP-GGUF Guide: unsloth.ai/docs/models/qwen3.6#mtp-guide
