Qwen3.6 now runs 2x faster with MTP GGUFs! Run locally on just 18GB RAM. ⚡️ MTP enables Qwen3.6 to generate ~1.4–2.2× faster with no accuracy change. Qwen3.6-27B MTP runs at 160 tokens/s. 35B-A3B reaches 240 t/s. GGUFs: huggingface.co/unsloth/Qwen3.6-27B-MTP-GGUF Guide: unsloth.ai/docs/models/qwen3.6#mtp-guide
May 18, 2026 at 1:42 PM
Something is afoot in the land of Qwen
I’m behind on writing about Qwen 3.5, a truly remarkable family of open weight models released by Alibaba’s Qwen team over the past few weeks. I’m hoping that the 3.5 …
Handsum: An LQIP Image File Format
Low Quality Image Placeholders (LQIPs) are very small (both in terms of file size and pixel dimensions) images that load very quickly, providing immediate visual feedback while full-resolution images load slowly in the background. They are small-in-file-size enough that it’s feasible to base64-encode and inline them into a web page, minimizing network round-trips and improving page load times.
How to Fix OpenClaw's Memory Search with QMD | Jose Casanova
Upgrade OpenClaw's memory search from basic SQLite to QMD — a local hybrid search engine combining BM25, vector search, and LLM re-ranking for better AI memory.
Physics of LM: Part 4.2, Canon Layers at Scale where Synthetic Pretraining Resonates in Reality
Serpentine software
I don’t usually write hot takes. But StrongDM’s Software Factory post is worth it, so here goes. Their post is elegant, short, and well-written, so I’m going to just go through a bunch of pull quotes. Compounding correctness long-horizon agentic coding workflows [now] compound correctness rather than error This is a big, empirical claim. I’m already convinced by my own experiences that agents, suitably scaffolded, can form a Brownian ratchet, such that pouring on more compute helps, on balance.
GrandPerspective — PDS edition
See where an atproto repository's bytes actually go, and act on what you find.
China Just Built What NVIDIA Feared Most. I Saw It
XiongjieDai/GPU-Benchmarks-on-LLM-Inference
Multiple NVIDIA GPUs or Apple Silicon for Large Language Model Inference?
Oxmgr — Rust Process Manager
42× faster crash recovery, 20× lower memory than PM2. Written in Rust.
Context Rot: How Increasing Input Tokens Impacts LLM Performance
Claude Sonnet 4, GPT-4.1, Qwen3-32B, and Gemini 2.5 Flash on Repeated Words Task

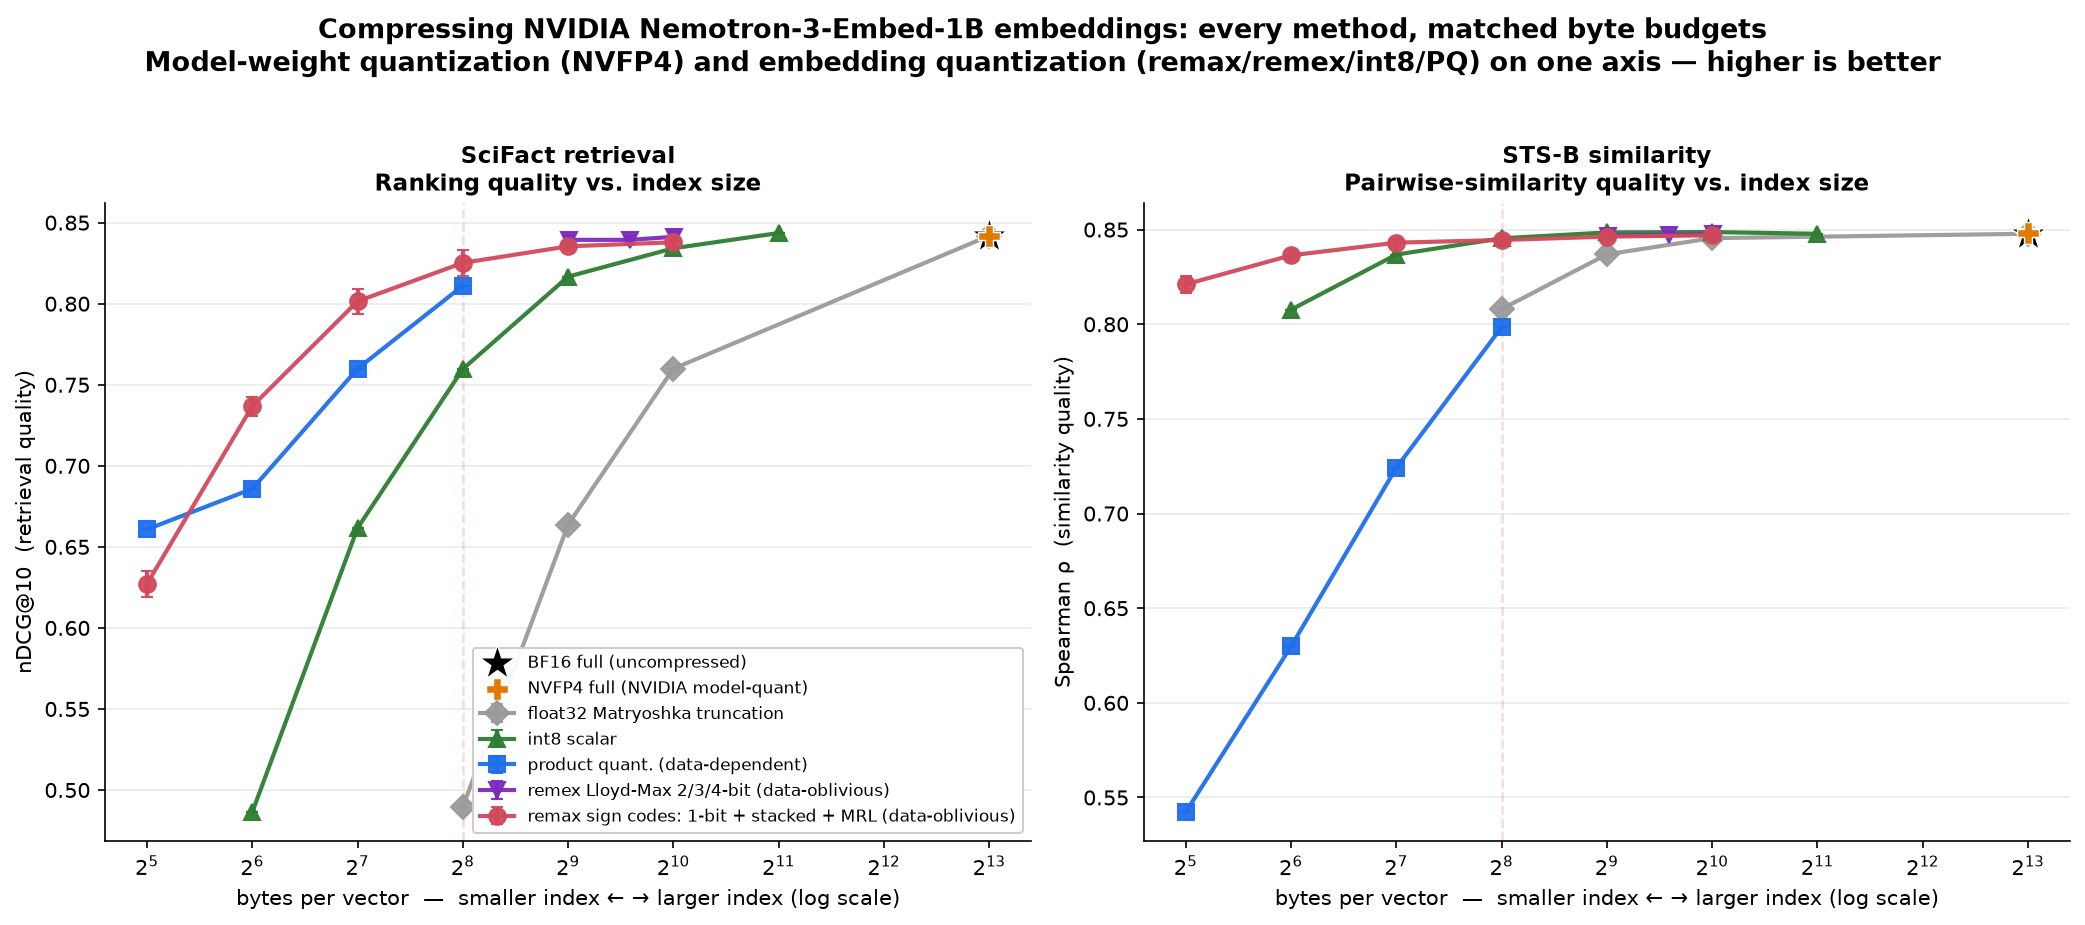
A 4-Bit Model and a 1-Bit Index
Running NVFP4 Nemotron on a CPU, then mapping every embedding-compression method at matched byte budgets. The two quantizations compose.