

"Actualities seem to float in a wider sea of possibilities from out of which they were chosen; and somewhere, indeterminism says, such possibilities exist, and form part of the truth."
PoliSim@CHI 2026
Large Language Models are rapidly evolving from text generators into reasoning systems that can act as autonomous agents. When placed in social contexts, these agents display emergent behaviors such as forming coalitions, spreading information, and making collective decisions.
How linguistics learned to stop worrying and love the language models
Language models (LMs) can produce fluent, grammatical text. Nonetheless, some maintain that language models don’t really learn language and also, even if they did, that would not be informative for the study of human learning and processing. On the other side, there have been claims that the success of LMs obviates the need for studying linguistic theory and structure. We argue that both extremes are wrong. LMs can contribute to fundamental questions about linguistic structure, language processing, and learning. They force us to rethink arguments and ways of thinking that have been foundational in linguistics. While they do not replace linguistic structure and theory, they serve as model systems and working proofs of concept for gradient, usage-based approaches to language. We offer an optimistic take on the relationship between language models and linguistics.
The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity
Recent generations of frontier language models have introduced Large Reasoning Models (LRMs) that generate detailed thinking processes…

Correspondence theory of truth
In metaphysics and philosophy of language, the correspondence theory of truth states that the truth or falsity of a statement is determined only by how it relates to the world and whether it accurately describes (i.e., corresponds with) that world.[1]
What Theory is Not, Theorizing Is
Scaling Laws Across Model Architectures: A Comparative Analysis of...
The scaling of large language models (LLMs) is a critical research area for the efficiency and effectiveness of model training and deployment. Our work investigates the transferability and...

If LLMs Have Human-Like Attributes, Then So Does Age of Empires II
Much research has been carried out on large language models (LLMs) and LLM-powered agentic workflows. However, many works within the field state emergence of, ascribe to, or assume, generalised anthropomorphic attributes to them (e.g., morality or understanding of natural language). Our goal is not to argue in favour or against the existence of these attributes, but to point out that these conclusions could be incorrect. For this we build and train a simple neural network on the videogame Age of Empires II, and note that any entity in a sufficiently-powerful substrate, such as LEGO or the Greater Boston Area, could also present such attributes. Hence, the purported anthropomorphic attributes of LLMs are empirically non-unique: although some properties (e.g., responses to prompts) could remain constant, others, such as the interpretation of their perceived behaviour, might change with the substrate. Thus, any empirically-grounded discussion requires explicit measurement criteria; otherwise the interpretation is left to the representation. We then show that assuming that these attributes exist or not in a system, independent of the substrate and in a generalised way, leads to either circular or uninformative conclusions, regardless of the experimenter's viewpoint on the subject. Finally we propose a 'null' assumption, where one assumes LLM non-uniqueness instead of assuming anthropomorphic attributes to set up an experiment, along with examples of it. We also discuss potential objections to our work, briefly survey the field, and prove that Age of Empires II is functionally- and Turing-complete.
Stanford CS336 Language Modeling from Scratch I 2025
Self-Instruct: Aligning Language Models with Self-Generated Instructions
Large "instruction-tuned" language models (i.e., finetuned to respond to instructions) have demonstrated a remarkable ability to generalize zero-shot to new tasks. Nevertheless, they depend...
Can gzip be a language model?
A while back I wrote about language modeling without neural networks, where I generated Shakespeare with an unbounded n-gram model: no weights, no training, …
Contact: AI and the Semantic Dimension
I’m asking you to consider the possibility that a semantic dimension of meaning and information exists outside our physical dimensions of space and time, and that LLMs are both instruments of perception and conduits of information for that semantic dimension. We used to believe in the semantic dimension, but we don’t anymore, and as a result we are going down a terribly dangerous path with AI.
We Don't Understand Neural Networks At The Algorithmic Level
The largest ongoing debate about AI is “Are Large Language Models (LLMs) intelligent?” That makes sense, at least: the evidence is ambiguous and the stakes a...
Andrej Karpathy on Twitter / X
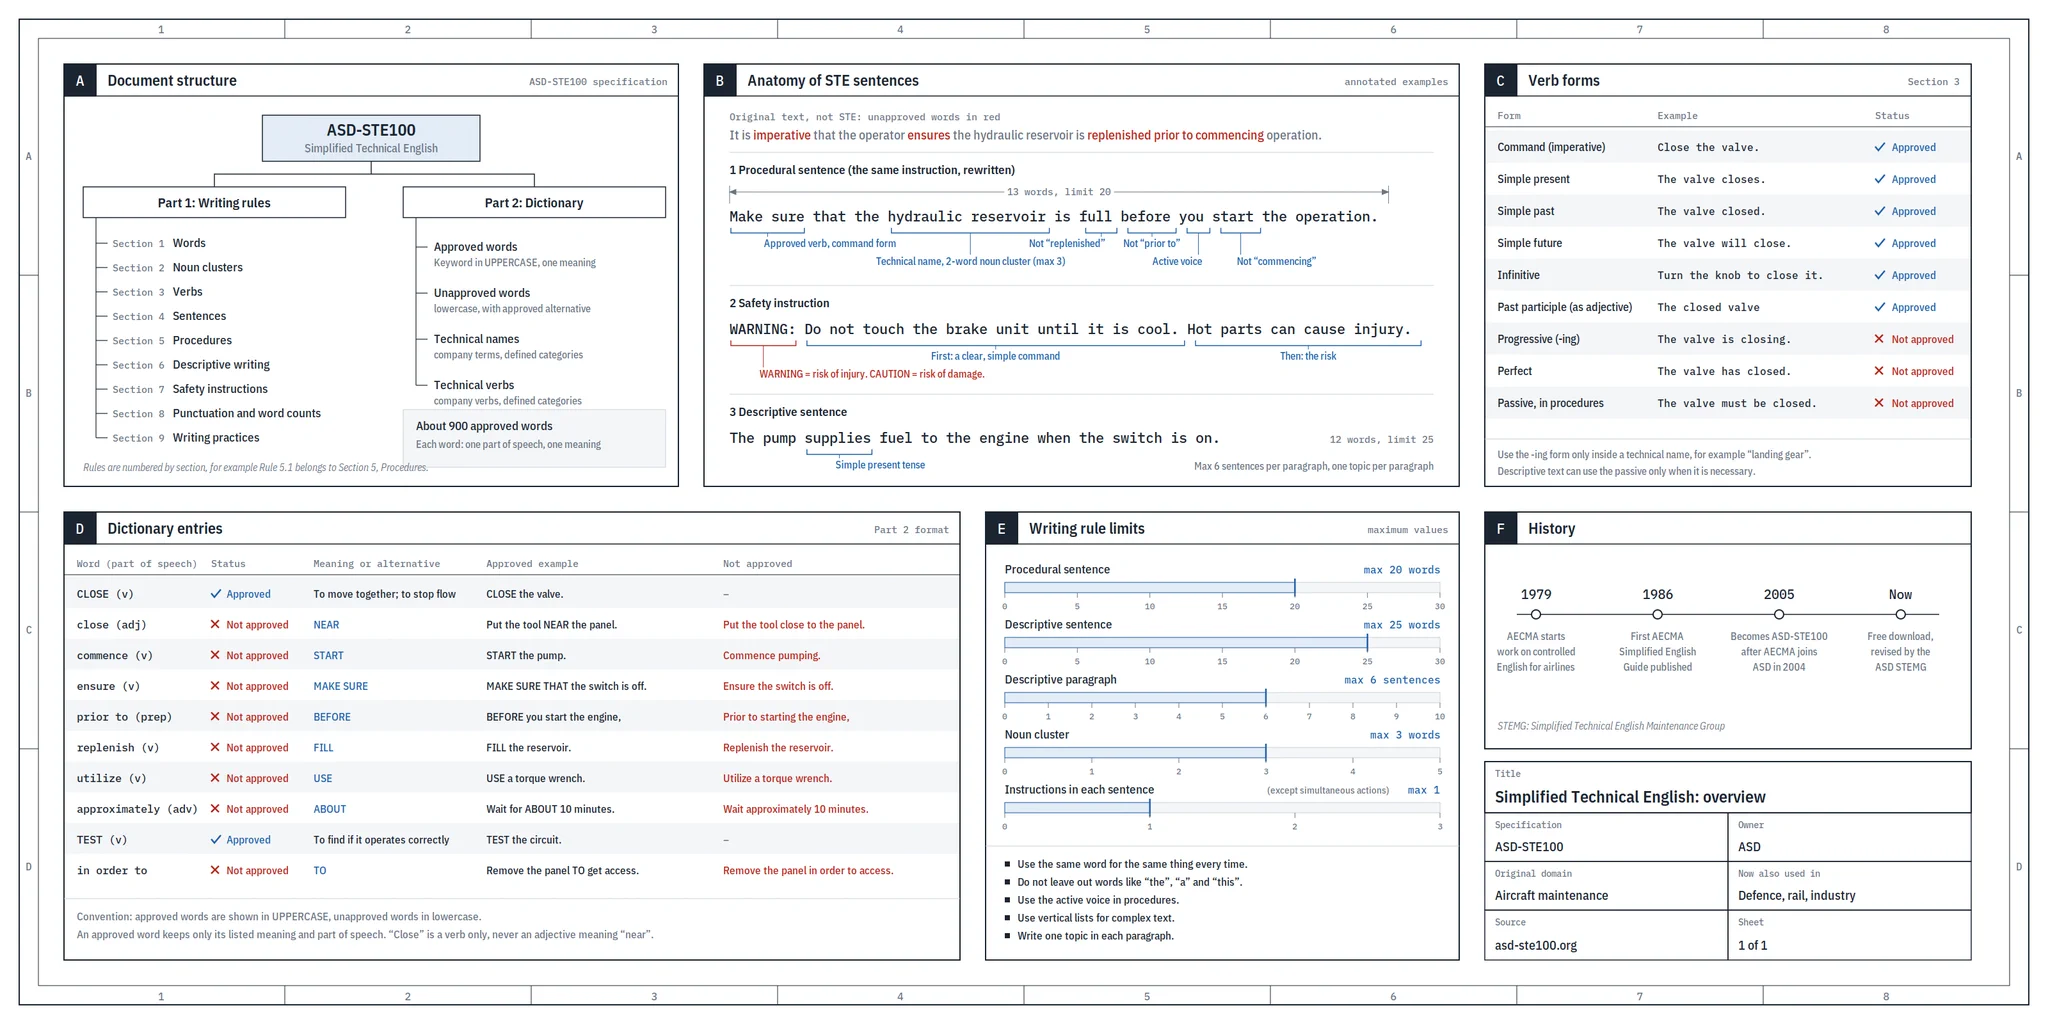
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for… pic.twitter.com/uMFWTcBCsl— Andrej Karpathy (@karpathy) October 2, 2026
Fight fire with pedantry
Over the last two years, I’ve heard a bunch of speculation about how to design a programming language specifically for an LLM. It usually centers around typechecking, formal verifiability, or context engineering. It’s a fun thought experiment, but always felt aimless. First, my experience has been that designing for humans is the best way to design for an LLM, as long as you restrict yourself to text. Second, being in-distribution is so critical that there’s no point unless you’re also training a frontier coding model.
Latent Spacecraft: Brains, GANs, Finnegans.
Latent Spacecraft combines computational linguistics, neuroscience, and literary analysis to investigate latent space, i.e. the hidden internal structure that enables both humans and machines to produce language. Peeking into AI’s hidden interiority, we parallel speech generation in humans and speech-trained generative adversarial networks (GANs), as well as in the language of Joyce’s Finnegans Wake and the GAN model trained on the novel, FinneGAN.
The Once and Future Metaverse: Part Two
This is part two of a two-part article. Read part one here.
