

Translate texts & full document files instantly. Accurate translations for individuals and Teams. Millions translate with DeepL every day.
Kagi Translate
Kagi Translate uses powerful AI models to instantly and accurately translate any content in any language.
EsDictionary - The EsDeeKid Translator
QC - The Quarantine Collective Translation Project
Collaborative translation review platform
Unix system programming in OCaml
Translation by Daniel C. Bünzli, Eric Cooper, Eliot Handelman, Priya Hattiangdi, Thad Meyer, Prashanth Mundkur, Richard Paradies, Till Varoquaux, Mark Wong-VanHaren

Dictionary Compression is finally here, and it's ridiculously good
Dictionary compression could completely change how applications send data over the web. It's recently gained broad support, and offers absurd real-world...
DASL — Data-Addressed Structures & Links
A small set of simple, standard primitives to work on content-addressed data.
DASL — Data-Addressed Structures & Links
A small set of simple, standard primitives to work on content-addressed data.
There are no lossless transformations of natural-language text
In my work at Clay I recently wrote an internal policy on acceptable use of AI writing by engineers, and I’m sharing it here. It’s my hope that one day better AI tools might be able to help us think, but until then I fear that using AI to write does the exact opposite.
DatologyAI on Twitter / X
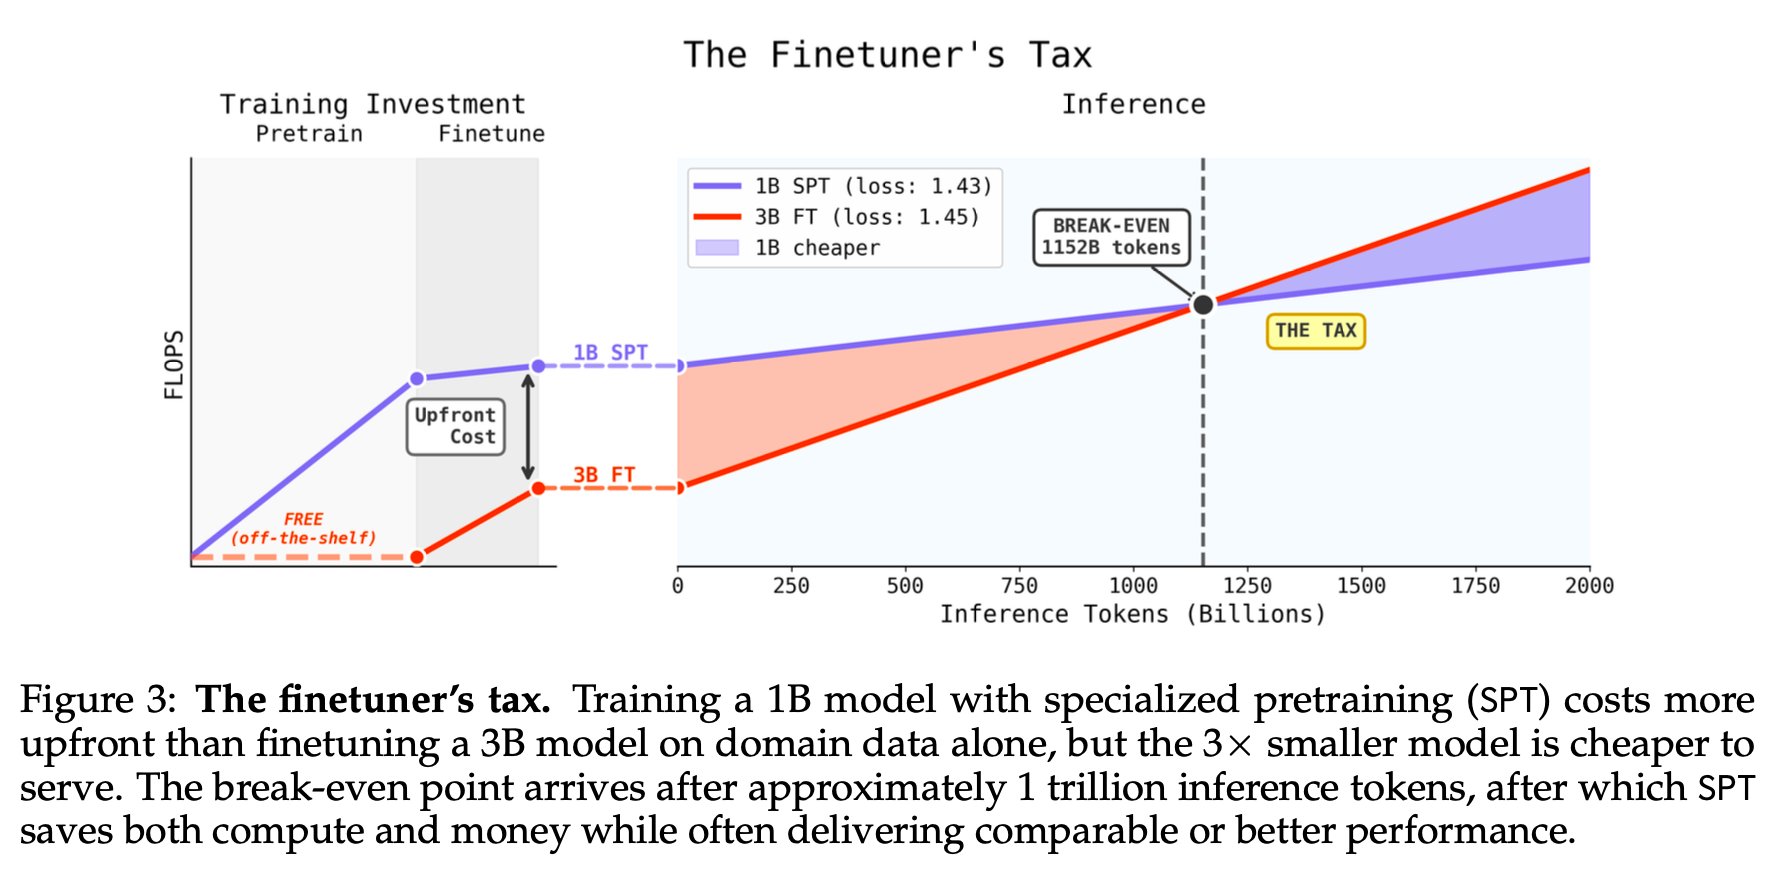
New Datology Research: We expose "The Finetuner's Fallacy"The standard approach to domain adaptation (pretrain on web data, finetune on your data) is leaving performance on the table.Mixing just 1-5% domain data into pretraining, then finetuning, produces a strictly better… pic.twitter.com/dXisEz96Vi— DatologyAI (@datologyai) March 18, 2026
Self-Instruct: Aligning Language Models with Self-Generated Instructions
Large "instruction-tuned" language models (i.e., finetuned to respond to instructions) have demonstrated a remarkable ability to generalize zero-shot to new tasks. Nevertheless, they depend...

Machine Learning Glossary | Google for Developers
This glossary defines a wide range of machine learning terms, including those specific to TensorFlow and large language models.
ST-MoE: Designing Stable and Transferable Sparse Expert Models
Scale has opened new frontiers in natural language processing -- but at a high cost. In response, Mixture-of-Experts (MoE) and Switch Transformers have been proposed as an energy efficient path to even larger and more capable language models. But advancing the state-of-the-art across a broad set of natural language tasks has been hindered by training instabilities and uncertain quality during fine-tuning. Our work focuses on these issues and acts as a design guide. We conclude by scaling a sparse model to 269B parameters, with a computational cost comparable to a 32B dense encoder-decoder Transformer (Stable and Transferable Mixture-of-Experts or ST-MoE-32B). For the first time, a sparse model achieves state-of-the-art performance in transfer learning, across a diverse set of tasks including reasoning (SuperGLUE, ARC Easy, ARC Challenge), summarization (XSum, CNN-DM), closed book question answering (WebQA, Natural Questions), and adversarially constructed tasks (Winogrande, ANLI R3).
dict.cc | English-Dutch dictionary | Engels-Nederlands woordenboek
dict.cc English-Dutch dictionary - Engels-Nederlands woordenboek - Dutch-English translations.